Kimi Chat Completion API Application and Usage
Kimi is an AI model series launched by Moonshot AI. Currently, kimi-k3.1-pro is recommended, suitable for long-horizon programming, complex reasoning, visual understanding, and knowledge work; kimi-k3 is still available. It is called through the OpenAI-compatible Chat Completions API.
This document mainly introduces the usage process of Kimi Chat Completion API operations. With it, we can easily use the official Kimi chat function.
¶ Application Process
To use Kimi Chat Completion API, first obtain your API Token from the Fishapi Cloud Console and keep it for later use.

If you have not logged in or registered yet, you will be automatically redirected to the login page to register and log in. After completion, you will automatically return to the current page.
One API Token can call all platform services; there is no need to apply separately for each service. The first application includes free credits for a free trial; when credits are insufficient, you can recharge your general balance in the console.
📘 Full documentation: Kimi Chat Completion API →
¶ Basic Usage
Next, you can fill in the corresponding content in the interface, as shown in the image:
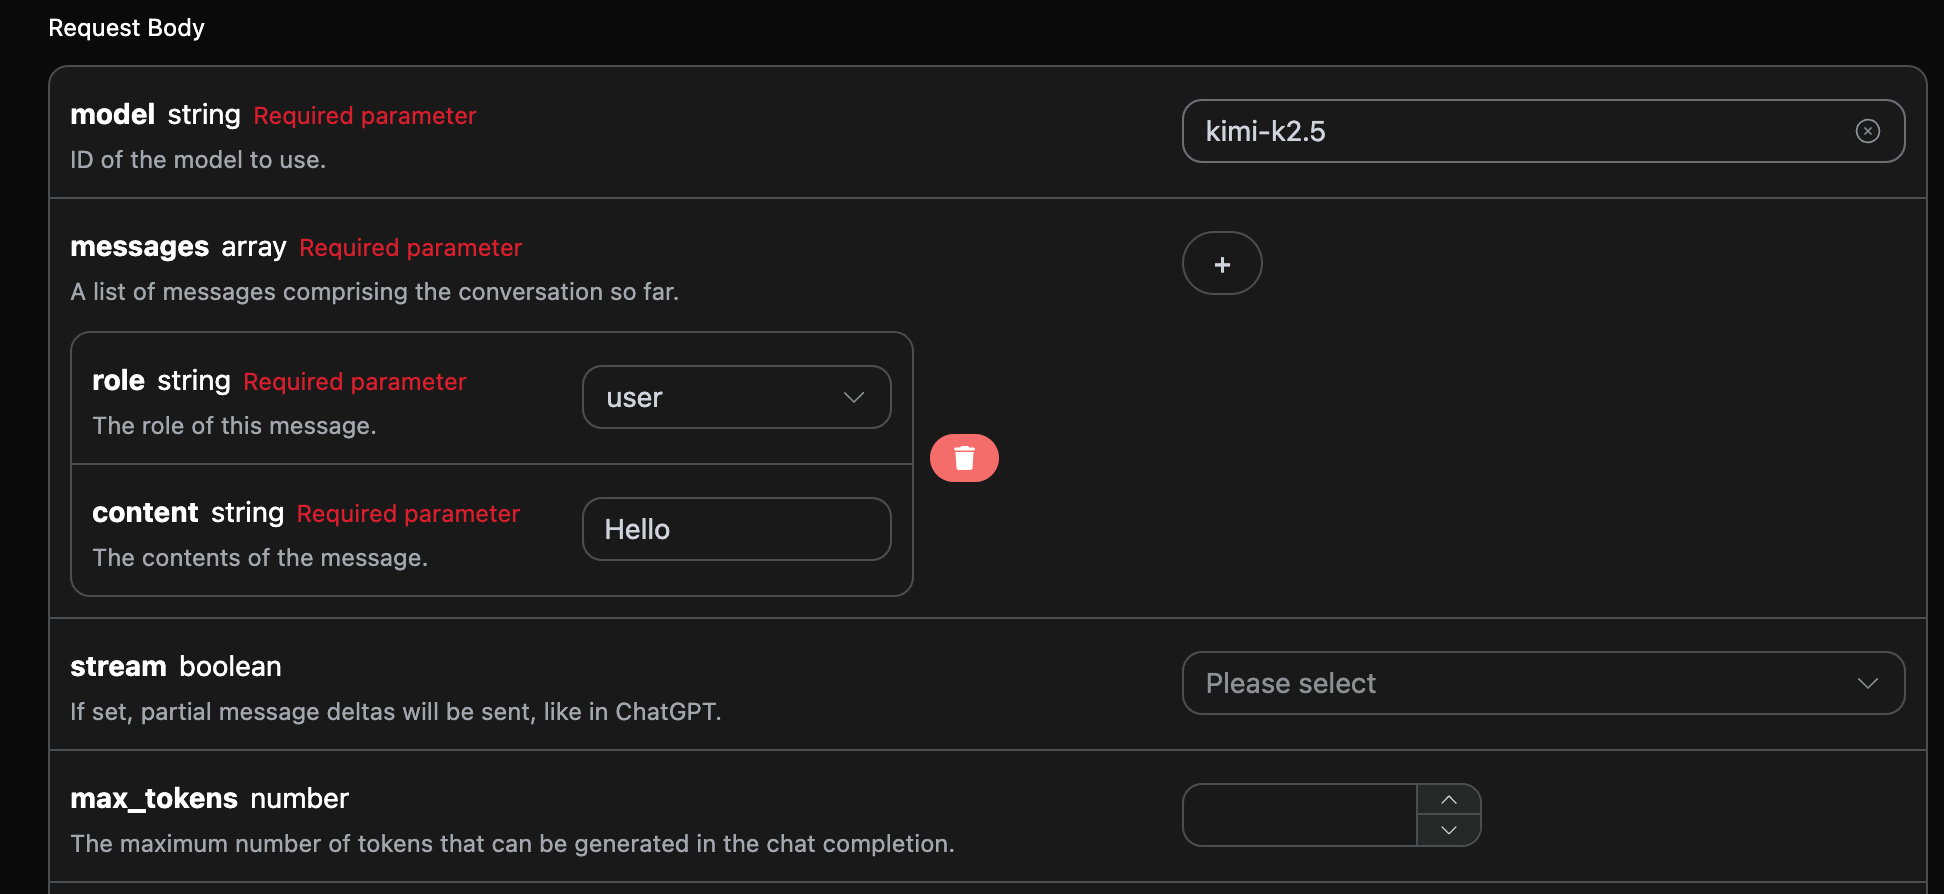
When using this API for the first time, you need to fill in at least three items: authorization can be selected directly from the dropdown list; model is used to select the Kimi model, and kimi-k3.1-pro is recommended; messages is an array of chat messages, where each message includes role and content, and role supports user, assistant, system, and tool.
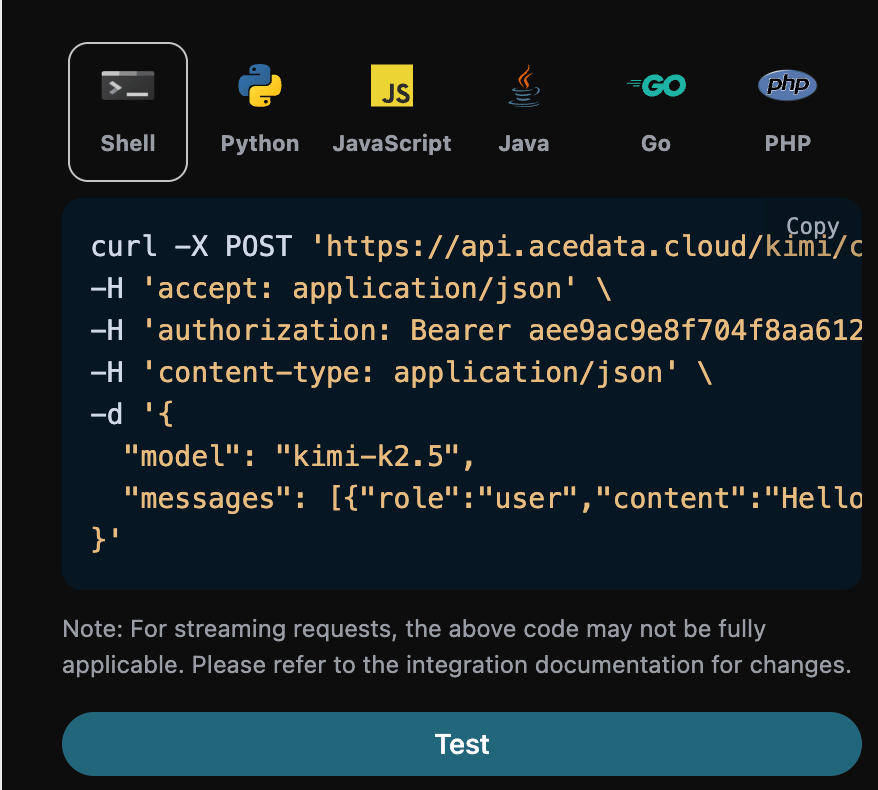
At the same time, you can notice the corresponding generated calling code on the right. You can copy the code and run it directly, or directly click the "Try" button for testing.
The following is a real K3 response obtained using reasoning_effort: max (unused extended fields omitted):
{
  "id": "msg_2D4Btbg1WgvkNE3tCYkR4xGA",
  "object": "chat.completion",
  "created": 1784466588,
  "model": "kimi-k3",
  "choices": [
    {
      "index": 0,
      "message": {
        "role": "assistant",
        "content": "Hello! How can I help you today?"
      },
      "logprobs": null,
      "finish_reason": "stop"
    }
  ],
  "usage": {
    "prompt_tokens": 86,
    "completion_tokens": 206,
    "total_tokens": 292
  }
}
The returned result contains multiple fields, introduced as follows:
id, the ID generated for this chat task, used to uniquely identify this chat task.model, the selected Kimi official website model.choices, the response information provided by Kimi for the prompt.usage: statistical information on tokens for this Q&A session.
Among them, choices contains Kimi's response information. The choices inside it is Kimi's specific response information, as shown in the image.
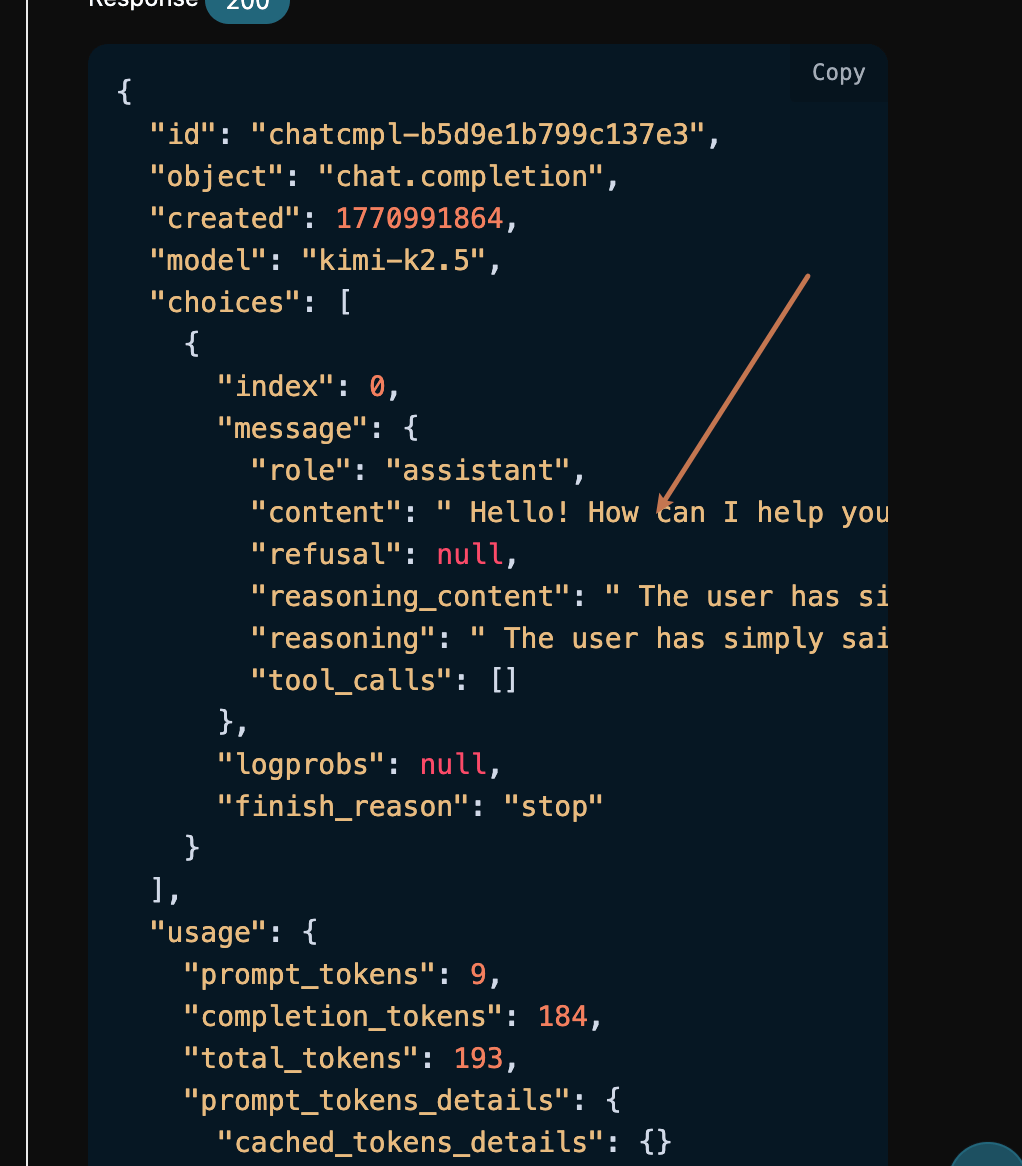
As you can see, the content field within choices contains the specific content of Kimi's reply; K3 may also return reasoning_content, which is used to represent the reasoning process.
¶ K3.1 Pro Reasoning Effort
kimi-k3.1-pro always enables reasoning. You can set reasoning_effort to low, high, or max at the top level of the request body; do not pass a configuration that disables reasoning. The model supports up to 1,048,576 tokens of context, but the actual request limit is still subject to the current API. Pricing is calculated based on input, output, and cache-hit usage. For details, see the Pricing card in the model catalog.
curl https://api.fishapi.cloud/kimi/chat/completions \
  -H "Authorization: Bearer $ACEDATACLOUD_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "kimi-k3.1-pro",
    "messages": [{"role": "user", "content": "审查这段代码并给出修复方案"}],
    "reasoning_effort": "low"
  }'
The following K3 example is retained for existing integrations, and the example response was indeed obtained from a K3 request.
¶ K3 Reasoning Effort
kimi-k3 always enables reasoning. The top level of the request body supports the reasoning_effort field, and the only currently supported value is max; when this field is omitted, max is also used. standard, high, or other strings may be leniently accepted by some compatible upstream providers, but they are not guaranteed to change reasoning behavior, so do not rely on them.
curl https://api.fishapi.cloud/kimi/chat/completions \
  -H "Authorization: Bearer $ACEDATACLOUD_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "kimi-k3",
    "messages": [{"role": "user", "content": "审查这段代码并给出修复方案"}],
    "reasoning_effort": "max"
  }'
When using the OpenAI SDK, you can pass this field directly:
response = client.chat.completions.create(
    model="kimi-k3",
    messages=[{"role": "user", "content": "设计一个可靠的任务队列"}],
    reasoning_effort="max",
)
For multi-turn conversations and tool calls, please return the complete assistant message from the previous turn to messages, including reasoning_content and tool_calls.
¶ Official References
- Thinking Effort: Explains that Kimi K3 always enables reasoning, and the only currently supported value for
reasoning_effortismax. - Model Parameter Reference: Compares reasoning parameters, context windows, and tool-calling differences between the K3 and K2 series.
- Create Chat Completion: Moonshot's official Chat Completions request, response, and OpenAPI field definitions.
¶ Streaming Responses
This API also supports streaming responses, which is very useful for web integration and can enable a word-by-word display effect on webpages.
If you want to return responses as a stream, you can change the stream parameter in the request header to true.
The modification is shown in the image, but the calling code needs corresponding changes to support streaming responses.
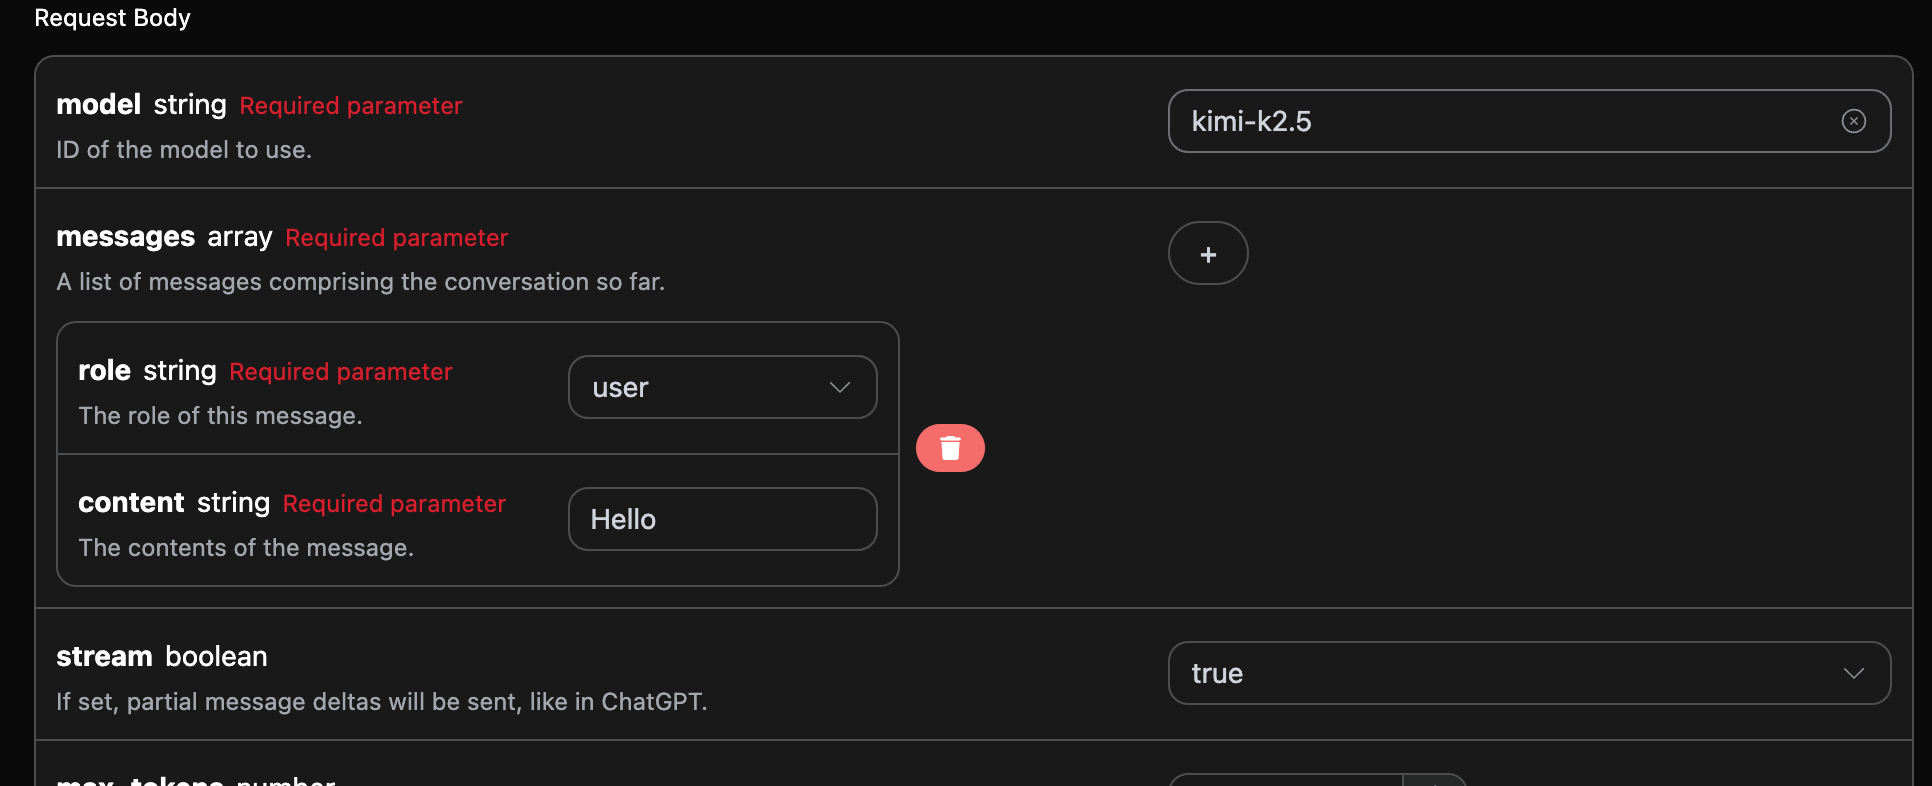
After changing stream to true, the API will return the corresponding JSON data line by line. At the code level, we need to make corresponding changes to obtain line-by-line results.
Python sample calling code:
import requests

url = "https://api.fishapi.cloud/kimi/chat/completions"

headers = {
    "accept": "application/json",
    "authorization": "Bearer {token}",
    "content-type": "application/json"
}

payload = {
    "model": "kimi-k3",
    "messages": [{"role":"user","content":"Hello"}],
    "reasoning_effort": "max",
    "stream": True
}

response = requests.post(url, json=payload, headers=headers)
print(response.text)
Below are excerpts from the start, reasoning, main text, end, and usage data blocks of the same real K3 Max streaming response:
data: {"id":"msg_er7WZjyv2kD3TG2yzbFPu5ZJ","object":"chat.completion.chunk","created":1784466598,"model":"kimi-k3","choices":[{"index":0,"delta":{"content":"","role":"assistant"},"finish_reason":null}],"usage":null}

data: {"id":"msg_er7WZjyv2kD3TG2yzbFPu5ZJ","object":"chat.completion.chunk","created":1784466598,"model":"kimi-k3","choices":[{"index":0,"delta":{"reasoning_content":"The"},"finish_reason":null}],"usage":null}

data: {"id":"msg_er7WZjyv2kD3TG2yzbFPu5ZJ","object":"chat.completion.chunk","created":1784466598,"model":"kimi-k3","choices":[{"index":0,"delta":{"content":"Hello"},"finish_reason":null}],"usage":null}

data: {"id":"msg_er7WZjyv2kD3TG2yzbFPu5ZJ","object":"chat.completion.chunk","created":1784466598,"model":"kimi-k3","choices":[{"index":0,"delta":{},"finish_reason":"stop"}],"usage":null}

data: {"id":"msg_er7WZjyv2kD3TG2yzbFPu5ZJ","object":"chat.completion.chunk","created":1784466598,"model":"kimi-k3","choices":[],"usage":{"prompt_tokens":172,"completion_tokens":168,"total_tokens":340}}

data: [DONE]
As you can see, there are many data entries in the response. The choices inside data contain the latest response content, which is consistent with the content introduced above. choices contains newly added response content, and you can integrate it into your system based on the result. At the same time, the end of a streaming response is determined based on the content of data. If the content is [DONE], it indicates that the streaming response has completely ended. The returned data result contains multiple fields, introduced as follows:
id, the ID generated for this conversation task, used to uniquely identify this conversation task.model, the selected Kimi official website model.choices, the response information provided by Kimi for the prompt.
JavaScript is also supported. For example, the Node.js streaming call code is as follows:
const options = {
  method: "POST",
  headers: {
    accept: "application/json",
    authorization: "Bearer {token}",
    "content-type": "application/json"
  },
  body: JSON.stringify({
    model: "kimi-k3",
    messages: [{ role: "user", content: "Hello" }],
    stream: true
  })
};

const response = await fetch("https://api.fishapi.cloud/kimi/chat/completions", options);
const reader = response.body.getReader();
const decoder = new TextDecoder("utf-8");
while (true) {
  const { value, done } = await reader.read();
  if (done) break;
  process.stdout.write(decoder.decode(value));
}
Java sample code:
JSONObject jsonObject = new JSONObject();
jsonObject.put("model", "kimi-k3");
jsonObject.put("messages", new JSONArray().put(new JSONObject().put("role", "user").put("content", "Hello")));
jsonObject.put("stream", true);
MediaType mediaType = MediaType.parse("application/json; charset=utf-8");
RequestBody body = RequestBody.create(jsonObject.toString(), mediaType);
Request request = new Request.Builder()
  .url("https://api.fishapi.cloud/kimi/chat/completions")
  .post(body)
  .addHeader("accept", "application/json")
  .addHeader("authorization", "Bearer {token}")
  .addHeader("content-type", "application/json")
  .build();

OkHttpClient client = new OkHttpClient();
Response response = client.newCall(request).execute();
System.out.println(response.body().string());
Other languages can be adapted separately. The principle is the same.
¶ Multi-turn Conversations
If you want to integrate multi-turn conversation functionality, you need to upload multiple prompts in the messages field. A specific example of multiple prompts is shown in the following image:
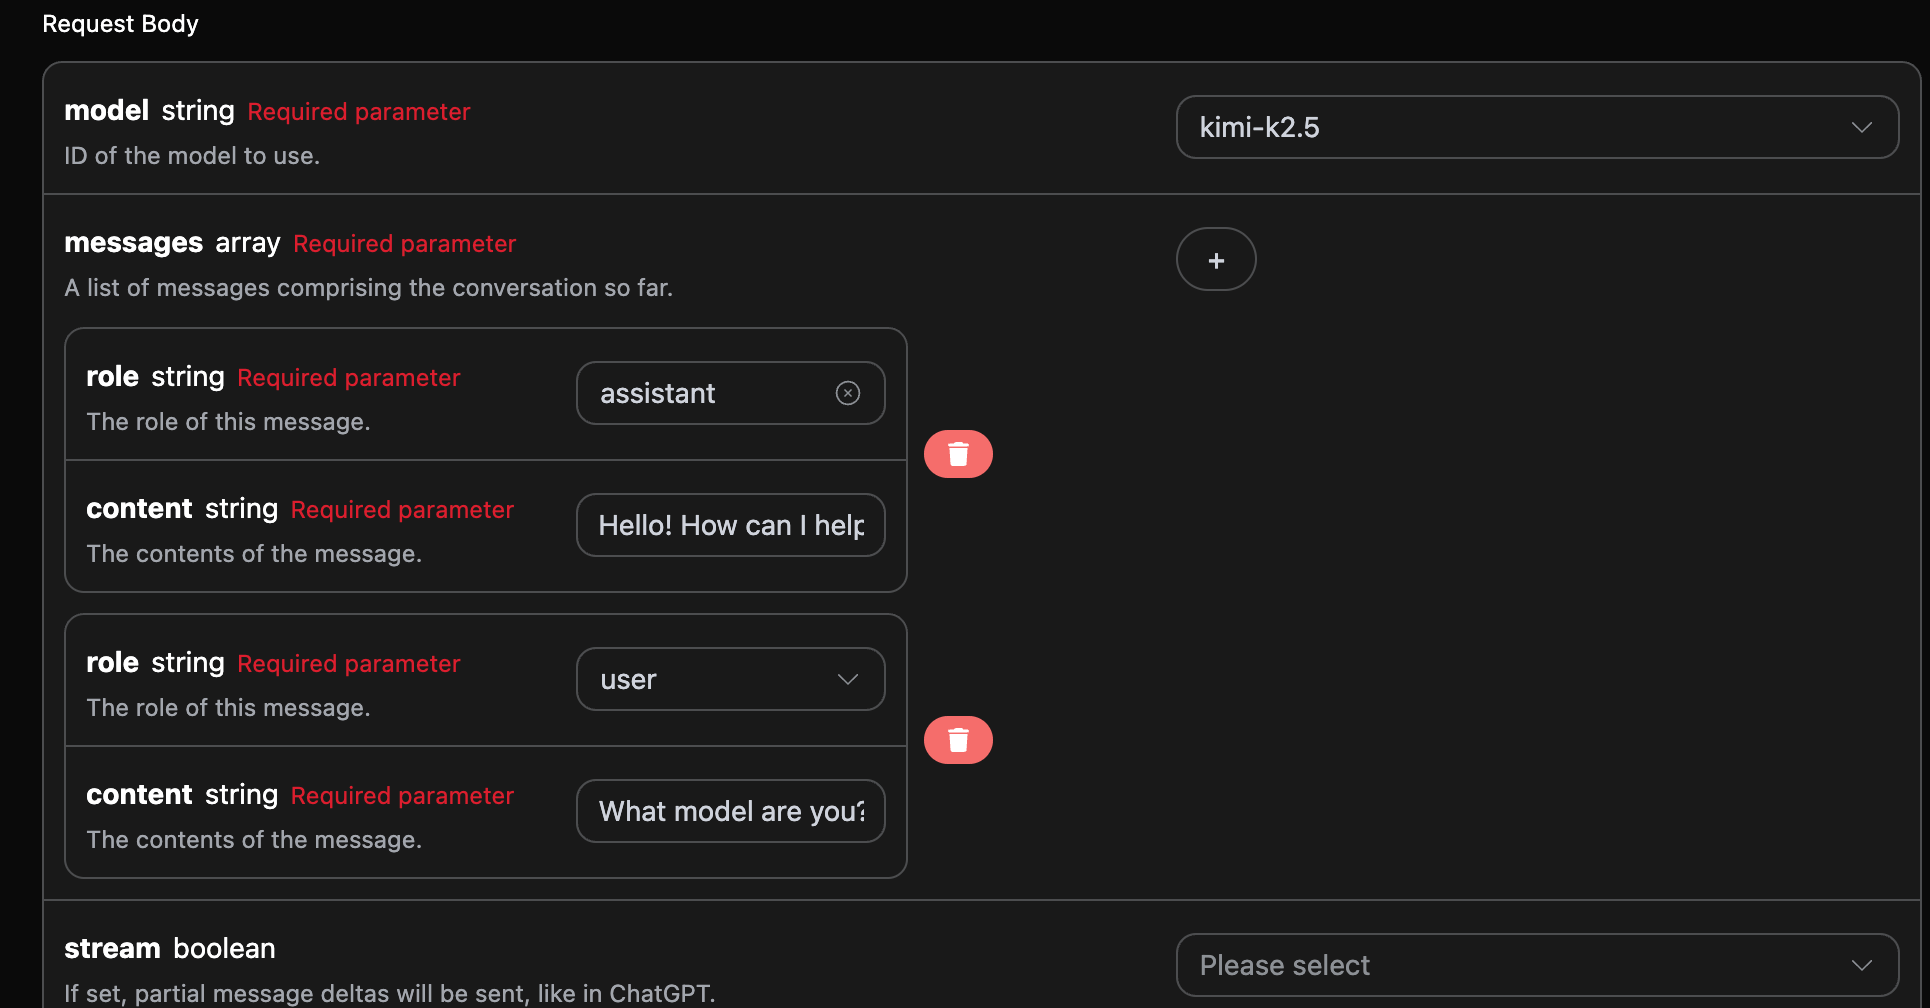
Python sample call code:
import requests

url = "https://api.fishapi.cloud/kimi/chat/completions"

headers = {
    "accept": "application/json",
    "authorization": "Bearer {token}",
    "content-type": "application/json"
}

payload = {
    "model": "kimi-k3",
    "messages": [{"role":"assistant","content":"Hello! How can I help you today?"},{"role":"user","content":"What model are you?"}],
    "reasoning_effort": "max"
}

response = requests.post(url, json=payload, headers=headers)
print(response.text)
By uploading multiple prompts, multi-turn conversations can be easily implemented. The following is a real K3 Max response obtained from this request (unused extended fields omitted):
{
  "id": "msg_Rqp8nPGBDHWwBlL4VpxuafOp",
  "object": "chat.completion",
  "created": 1784466628,
  "model": "kimi-k3",
  "choices": [
    {
      "index": 0,
      "message": {
        "role": "assistant",
        "content": "I’m Kimi, an AI assistant developed by Moonshot AI (月之暗面). I don’t have a specific public model version identifier to share from here."
      },
      "logprobs": null,
      "finish_reason": "stop"
    }
  ],
  "usage": {
    "prompt_tokens": 134,
    "completion_tokens": 346,
    "total_tokens": 480
  }
}
As you can see, the information contained in choices is consistent with the basic usage content. This contains the specific content of Kimi's responses to multiple conversations, allowing corresponding questions to be answered based on multiple conversation contents.
¶ Error Handling
When calling the API, if an error occurs, the API will return the corresponding error code and information. For example:
400 token_mismatched: Bad request, possibly due to missing or invalid parameters.400 api_not_implemented: Bad request, possibly due to missing or invalid parameters.401 invalid_token: Unauthorized, invalid or missing authorization token.429 too_many_requests: Too many requests, you have exceeded the rate limit.500 api_error: Internal server error, something went wrong on the server.
¶ Error Response Example
{
  "success": false,
  "error": {
    "code": "api_error",
    "message": "fetch failed"
  },
  "trace_id": "2cf86e86-22a4-46e1-ac2f-032c0f2a4e89"
}
¶ Conclusion
Through this document, you have learned how to use the Kimi Chat Completion API to implement regular conversations, streaming responses, multi-turn conversations, and control the reasoning strength of K3 through reasoning_effort.